Structural variants (SVs), such as deletions, duplications, insertions, and inversions of 50 base pairs or more, affect more of the genome than single-nucleotide variants and often have larger functional and evolutionary consequences. Long-read sequencing and de novo assembly now make SVs visible, but population genetics still lacks the models and tools to analyze them. My research builds these foundations, from reconstructing accurate haplotypes, to modeling SV evolution, to analyzing variation directly on pangenome graphs. Because populations evolve in space, I also develop spatially explicit models and machine-learning methods that infer population history across space and time. I apply these methods to a question that has run through all of my work: how archaic introgression and admixture shaped present-day human genetic variation and disease risk.
My research is organized around three themes:
- Haplotype reconstruction from long reads
- Population genetics of structural variation and pangenomes
- Spatially explicit models of population history
- Archaic introgression and admixture
Haplotype reconstruction from long reads
Accurate phasing of genetic variation is essential for association testing, clinical variant interpretation, and population history inference. Long reads greatly improve phasing continuity, but reconstructing chromosome-scale haplotypes, especially across INDELs and SVs, still often requires combining multiple sequencing technologies.
I developed LongHap, a read-based phasing method that jointly phases SNVs, INDELs, and SVs using loopy belief propagation, and can additionally integrate the 5-methylcytosine (5mC) signal that PacBio HiFi and Oxford Nanopore reads already carry. Across HiFi, ONT, and ultra-long ONT data, LongHap phases more INDELs and SVs than existing tools while maintaining lower error rates, extends phase blocks when methylation is included, and runs roughly 30× faster than methylation-aware alternatives. It also performs well on challenging, medically relevant genes and across genomes of diverse ancestry.
Leveraging Methylation Information in Long-Read Sequencing Data To Improve Variant Phasing
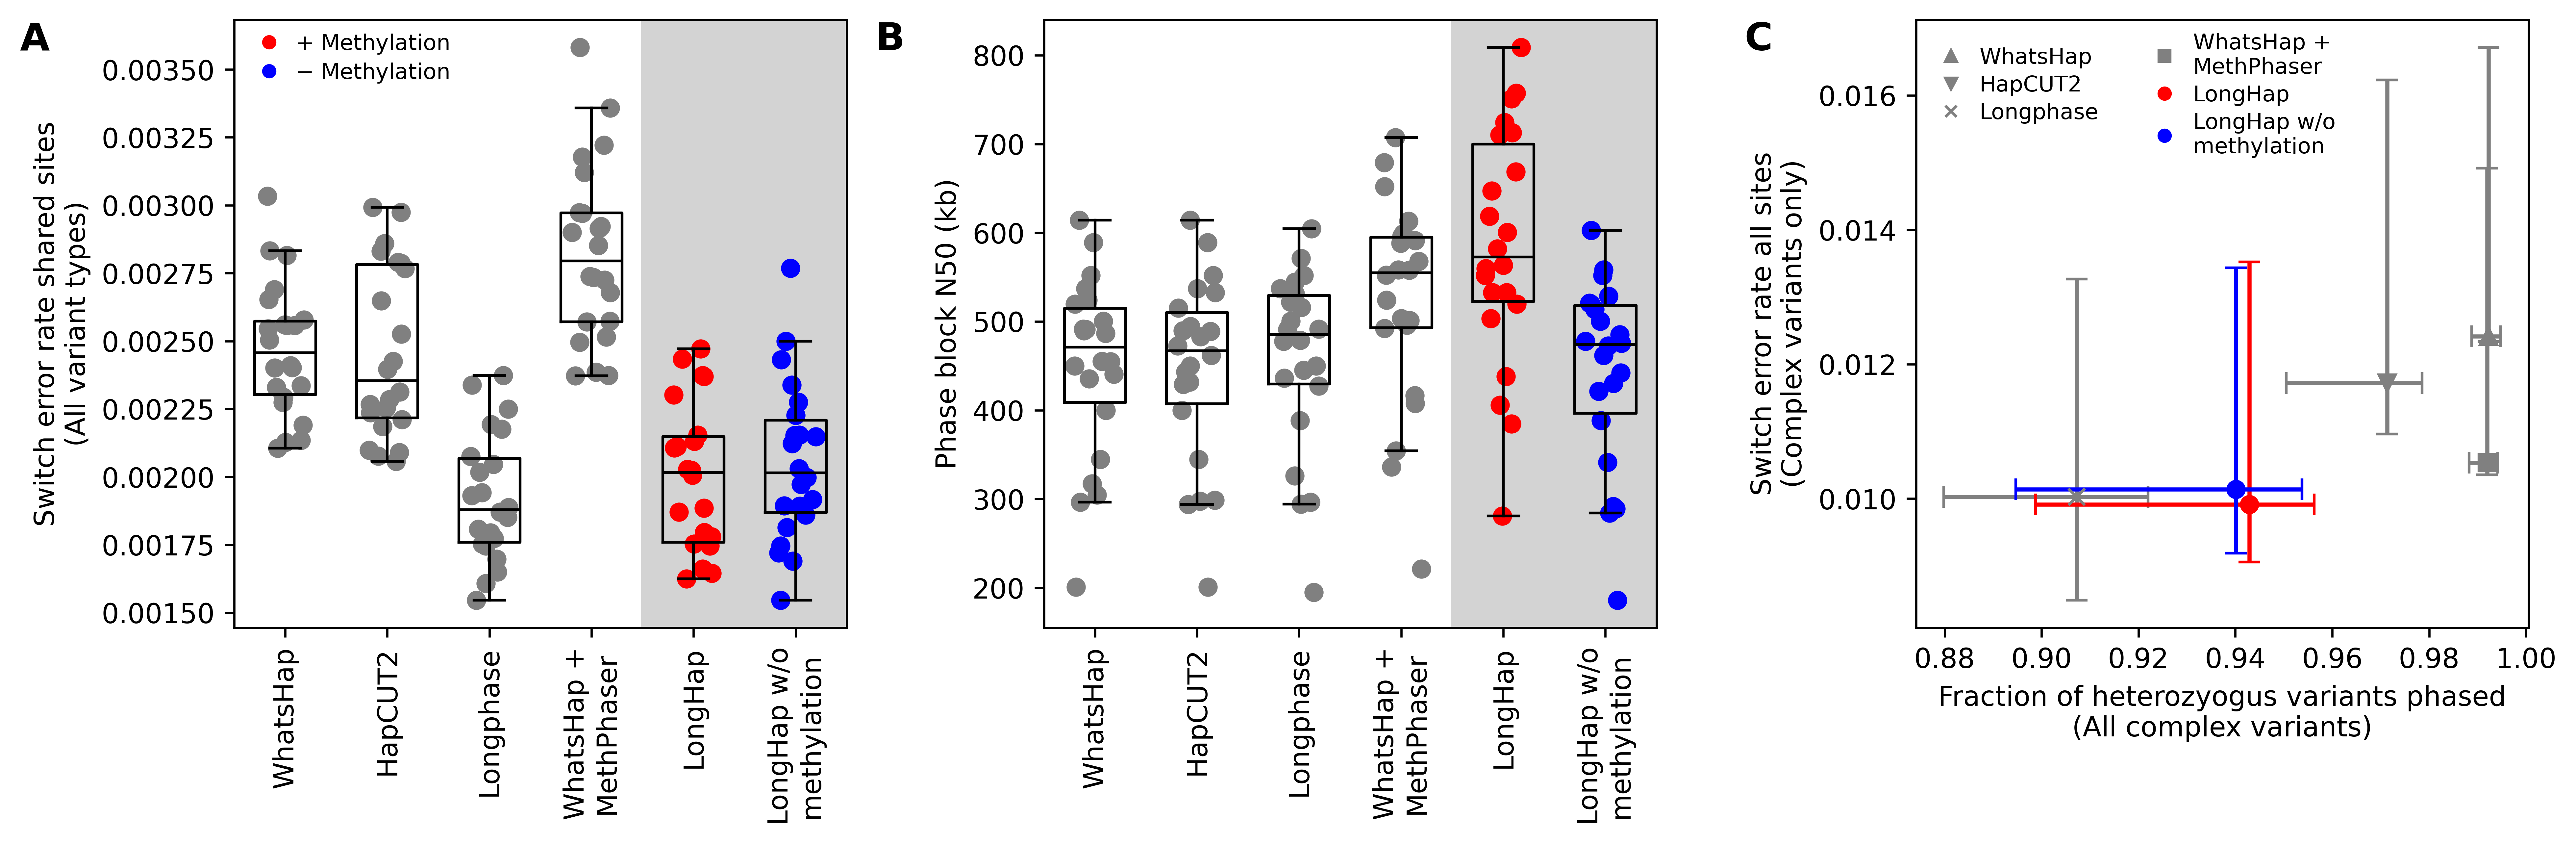
Accurate phasing of genetic and epigenetic variation is crucial for many downstream analyses, including association testing, clinical variant interpretation, and population history inference. Although long-read sequencing significantly improves the continuity and completeness of genome sequencing, reconstructing chromosome-scale haplotypes still often requires combining multiple technologies, such as PacBio HiFi and Oxford Nanopore Technologies (ONT) sequencing. Moreover, INDELs and structural variants (SVs) remain difficult to phase accurately, even though they are often the most functionally consequential variants, because the alleles that reads carry at these sites are frequently ambiguous or error-prone. To address this, I developed LongHap, a read-based phasing method that uses loopy belief propagation to jointly phase SNVs, INDELs, and SVs. LongHap phases more INDELs and SVs than existing read-based tools while maintaining lower error rates, including in challenging, medically relevant genes and across genomes of diverse ancestry (Figure 1). Because PacBio HiFi and ONT reads also detect the epigenetic modification 5-methylcytosine (5mC), LongHap can additionally integrate allele-specific methylation to connect variants in regions with few heterozygous sites, reducing switch error rates and increasing phase block contiguity at roughly 30-fold lower runtime than existing methylation-aware phasing workflows (Figure 1).
To extend these performance gains to phased de novo genome assemblies, I am now working to incorporate LongHap’s methylation-aware phasing module into an assembly polishing pipeline, improving haplotype accuracy in partially phased de novo genome assemblies generated from either PacBio HiFi or ONT sequencing data and reducing the need for multiple costly sequencing experiments that require large amounts of DNA.
Relevant work:
- Aaron Pfennig and Joshua M. Akey, Methylation-aware long-read phasing significantly improves genome-wide haplotype reconstruction, bioRxiv, https://doi.org/10.64898/2026.03.11.710820
Population genetics of structural variation and pangenomes
Models for structural variant evolution
SVs arise through mutational mechanisms, such as non-allelic homologous recombination, that violate basic assumptions of population genetics, including constant mutation rates. As a result, we lack the foundational models needed to make evolutionary and clinical inferences about them. I am developing theoretical frameworks that model these mechanisms directly. For example, copy number variants can be modeled as chromosomes switching between copy-number states, where two chromosomes can only coalesce when they share the same state. These models make it possible to build realistic simulations and to train inference methods, including machine-learning approaches, for questions about SV selection and history.
Population genetics on pangenome graphs
Pangenomes are a set of multiple whole-genome sequences typically represented as a graph (Figure 2). Unlike a single reference genome, pangenomes capture the full spectrum of genetic variation by being able to represent multiple mutations at the same position and accommodate substantial amounts of non-reference sequence.
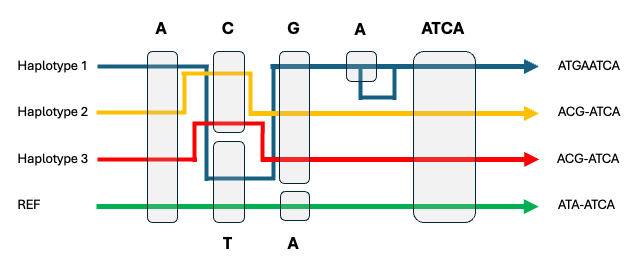
These capabilities are particularly critical for studying biomedically important highly diverse and structurally complex “genomic black holes” that are now accurately reconstructed in de novo genome assemblies.
Yet, most analyses still project pangenome variation back onto a single linear reference, discarding much of what assembly gained. I am developing graph-native methods for standard population and statistical genetics analyses, such as inferring population structure and shared ancestry, so that the full spectrum of variation, including complex SVs, can be used directly.
Structural variation in human evolution
I apply these approaches to SVs that shaped human diversity. With collaborators, I helped show that a Denisovan-derived Alu insertion in OCA2 contributes to pigmentation variation in present-day Melanesians.
Relevant work:
- Kwondo Kim, Aaron Pfennig (author 2 out of 12), …, and Charles Lee, A Denisovan-derived Alu insertion in OCA2 contributes to pigmentation diversity in present-day Melanesian, 2026, bioRxiv, https://doi.org/10.64898/2026.03.18.712481
Spatially explicit models of population history
Most population-genetic inference treats populations as randomly mating units without geography. Yet humans and other species evolve in continuous space, shaped by limited dispersal, range expansions, barriers to gene flow, and admixture where populations meet. Ignoring space can bias estimates of demography and selection, and it obscures where and when populations came into contact.
I am developing spatially explicit population-genetic models and simulation-based inference methods that recover population history across both space and time. Ancestral recombination graphs (ARGs), which encode the genealogical history of a sample along the genome, provide a rich input for this: I am building graph convolutional networks that learn directly from ARGs to infer spatiotemporal processes such as dispersal, migration, and the timing and location of admixture.
Archaic introgression and admixture
Admixture and introgression have played a central role in human evolution. I study how they shaped present-day genetic variation, using both theory and large-scale data.
Fitness of introgressed variation. I developed a population-genetic model showing that fitness effects arising from a heterogeneous hybrid background change the dynamics of focal alleles during introgression. The model predicts that most introgressed alleles must survive an initial filter, implying that Neanderthal variants remaining in human genomes are unlikely to be strongly deleterious.
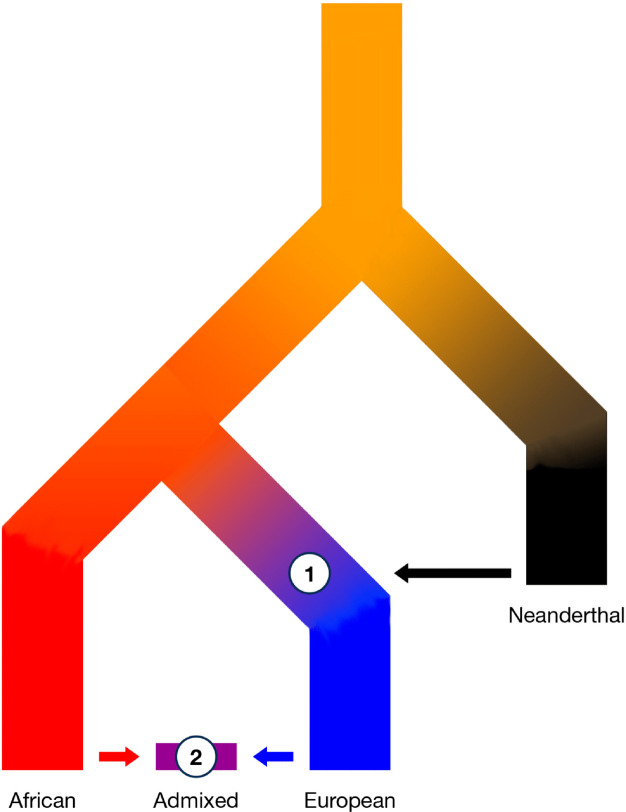
I tested this prediction in 30,780 recently admixed genomes from the United States, where Neanderthal sequence contributed mostly by European-like ancestors was placed on a largely African-like background (Figure 3). Admixed genomes carried about as much Neanderthal sequence as expected, indicating that the remaining Neanderthal ancestry is likely evolutionarily neutral and that widespread recent polygenic selection against it did not occur.
Sex-biased introgression and admixture. Contrasting ancestry on the X chromosome and autosomes can reveal whether males and females contributed unequally to admixed populations. I showed how uncertainty affects these estimates in the context of admixture in the Americas, and I am now using simulation-based inference (Approximate Bayesian Computation) to jointly estimate sex-biased contributions and selection during Neanderthal introgression.
Collaborative work includes studies of evolutionary genetics in African populations and the genetic architecture of prostate cancer and androgenetic alopecia in men of African ancestry.
Relevant work:
†These authors are co-corresponding authors
- Aaron Pfennig† and Joesph Lachance†, Limited selection on Neanderthal DNA in 30,780 recently admixed genomes with African-like ancestry, Molecular Biology and Evolution, 2026, https://doi.org/10.1093/molbev/msag136
- Aaron Pfennig and Joseph Lachance, Hybrid fitness effects modify fixation probabilities of introgressed alleles, G3 Genes|Genomes|Genetics, 2022, https://doi.org/10.1093/g3journal/jkac113
- Aaron Pfennig and Joseph Lachance, Challenges of accurately estimating sex-biased admixture from X chromosomal and autosomal ancestry proportions, The American Journal of Human Genetics, 2023, https://doi.org/10.1016/j.ajhg.2022.12.012
- Aaron Pfennig, Lindsay N Petersen, Paidamoyo Kachambwa, Joseph Lachance, Evolutionary genetics and admixture in African populations, Genome Biology and Evolution, 2023, https://doi.org/10.1093/gbe/evad054
- Rohini Janivara, Ujani Hazra, Aaron Pfennig (author 3 out of 22), …, and Joseph Lachance, Uncovering the genetic architecture and evolutionary roots of androgenetic alopecia in African men, Human Genetics and Genomics Advances, 2025, https://doi.org/10.1016/j.xhgg.2025.100428
- Burcu F. Darst, Raymond Hughley, Aaron Pfennig (author 3 out of 101), …, and Christopher A. Haiman, A Rare Germline HOXB13 Variant Contributes to Risk of Prostate Cancer in Men of African Ancestry, Eur Urol, 2022, https://doi.org/10.1016/j.eururo.2021.12.023